

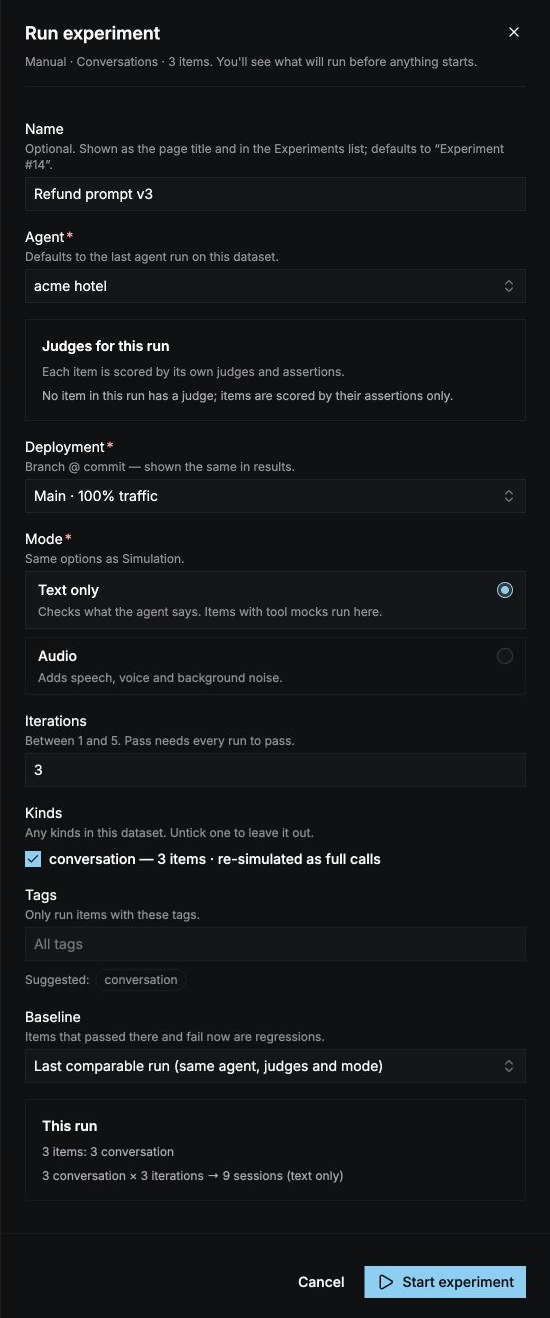
Configure the run
1
Name
Optional. Shown as the page title and in the experiments list, for example Refund prompt v3. Defaults to Experiment #N.
2
Agent
The agent to test. Defaults to the agent last run on this dataset. A dataset doesn’t belong to one agent, so you can run any agent against it.
3
Deployment
The branch to test. It defaults to the agent’s default branch, and results show it as branch @ commit. An experiment tests what’s deployed on the branch, not your draft. See Deploy an agent.
4
Mode
The same modes as Simulation:
- Text only: checks what the agent says. Items with tool mocks run here.
- Audio: adds speech, voice, and background noise.
5
Iterations
How many times each item runs, from 1 to 5. Defaults to 1.Agents don’t answer the same way every time, so one run can pass by luck. With more iterations, an item that passes every time gets Pass, and one that passes only some of the time gets Flaky, which points to a weak spot. See Verdicts.
6
Kinds and tags
Every kind in the dataset starts ticked; untick one to leave it out. Pick Tags to run only the items with those tags. When you run selected items, these filters don’t appear.
7
Baseline
The experiment to compare with. Items that passed there and fail now are regressions. Defaults to Last comparable run (same agent, judges and mode), or pick any completed experiment on this dataset.
Judges
There are no judges to pick: each item is scored by its own judges and assertions. Under Judges for this run, the panel lists every judge the items use and how many items use each. If a judge an item uses was deleted, the panel says so. Those items aren’t scored by it; edit them to pick another judge.What runs
Before you start, the bottom of the panel shows what will run:- Single-stage items (LLM, STT, TTS, turn detection, and VAD) run together in one quick batch that finishes first, for example 12 llm · 4 stt items → 1 component batch.
- Conversation items run as simulated calls, one per iteration, for example 3 conversation × 3 iterations → 9 sessions (text only). These take longer.
Archived items never run. If no active items match the kinds and tags you picked, the panel says what to change.